
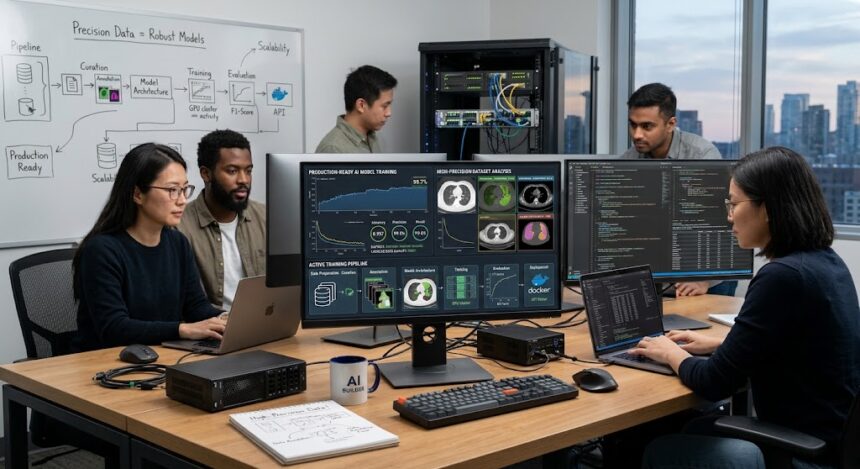
Launching functional artificial intelligence applications has become significantly easier thanks to open-source foundation models and cloud infrastructure. Engineering teams can assemble an impressive prototype in a matter of days. However, moving from an early demo to a reliable, production-ready product exposes a persistent bottleneck: the quality and accuracy of the underlying training data.
Many software teams spend weeks tuning model architectures or adjusting hyperparameters, only to discover that edge-case failures stem from noisy, inconsistent, or incorrectly labeled datasets. In commercial machine learning applications, model performance is strictly bound by the quality of the data used to train it.
The Hidden Friction in Dataset Preparation
Collecting, cleaning, and annotating data for complex algorithms is a labor-intensive process that frequently pulls core engineering teams away from primary product development. When developers spend hours manually categorizing images, verifying text prompts, or timestamping audio files, feature roadmaps inevitably slip.
Outsourcing dataset preparation to unverified crowdsourcing platforms introduces separate operational risks. Without rigorous quality control and clear annotation guidelines, inconsistent workers introduce noise into the dataset. Mislabeled visual objects, flawed sentiment scores, or inaccurate audio transcriptions confuse models during training runs. This results in costly retraining cycles and unpredictable behavior once the product goes live.
Furthermore, training conversational tools or natural language processing models for global deployment requires authentic regional datasets. Sourcing localized speech patterns, distinct dialects, and domain-specific terminology is virtually impossible without access to native linguistic talent.
Accelerating Machine Learning Pipelines with Technolex
To train reliable algorithms without draining internal development resources, technology leaders implement structured, human-in-the-loop data workflows.
Partnering with an established provider of ai training data services like Technolex enables organizations to scale their data collection, labeling, and validation operations efficiently. Technolex builds dedicated project teams composed of native linguists and subject-matter experts who handle complex text categorization, audio transcription, and Reinforcement Learning from Human Feedback (RLHF) tasks with high precision.
Protecting Model Integrity at Scale
In an industry where algorithms and computing power are widely accessible, proprietary high-quality datasets represent your primary competitive advantage. By stepping away from unverified crowdsourcing and partnering with a specialized provider like Technolex, companies build more resilient models, minimize deployment risks, and bring high-impact AI solutions to market faster.